Service 07 of 10 · Technology & Intelligence

Your tools, connected, with engineers on call after launch.

We connect online shops, payments, accounting and customer records for new and growing businesses and enterprises. Staff type each order once. If a link fails, our engineers fix it within an agreed time.

Typical length
4–10 weeks per phase
Approach
Custom or ready-made
Support
Agreed response times

Behind the heading, a train-map style drawing joins a typical company’s tools. They are an online shop, payments, ERP, warehouse, CRM, support desk, email, analytics and data warehouse. Lines for orders, customers and data meet at one hub. Updates move along each line.

$ the problem 30 tools · 15 copy-and-paste jobs

Tools that don’t talk leave staff copying data by hand.

Staff retype orders into the ERP (stock and accounts). Customer records in the CRM are fixed by hand. Nightly exports fail without warning.

A board of thirty business tools. Today, staff copy data by hand fifteen times between them, through files such as Orders.xlsx, Leads.csv and a stock sheet. Connected, one line links every tool, and six spreadsheets and duplicate tools are retired.

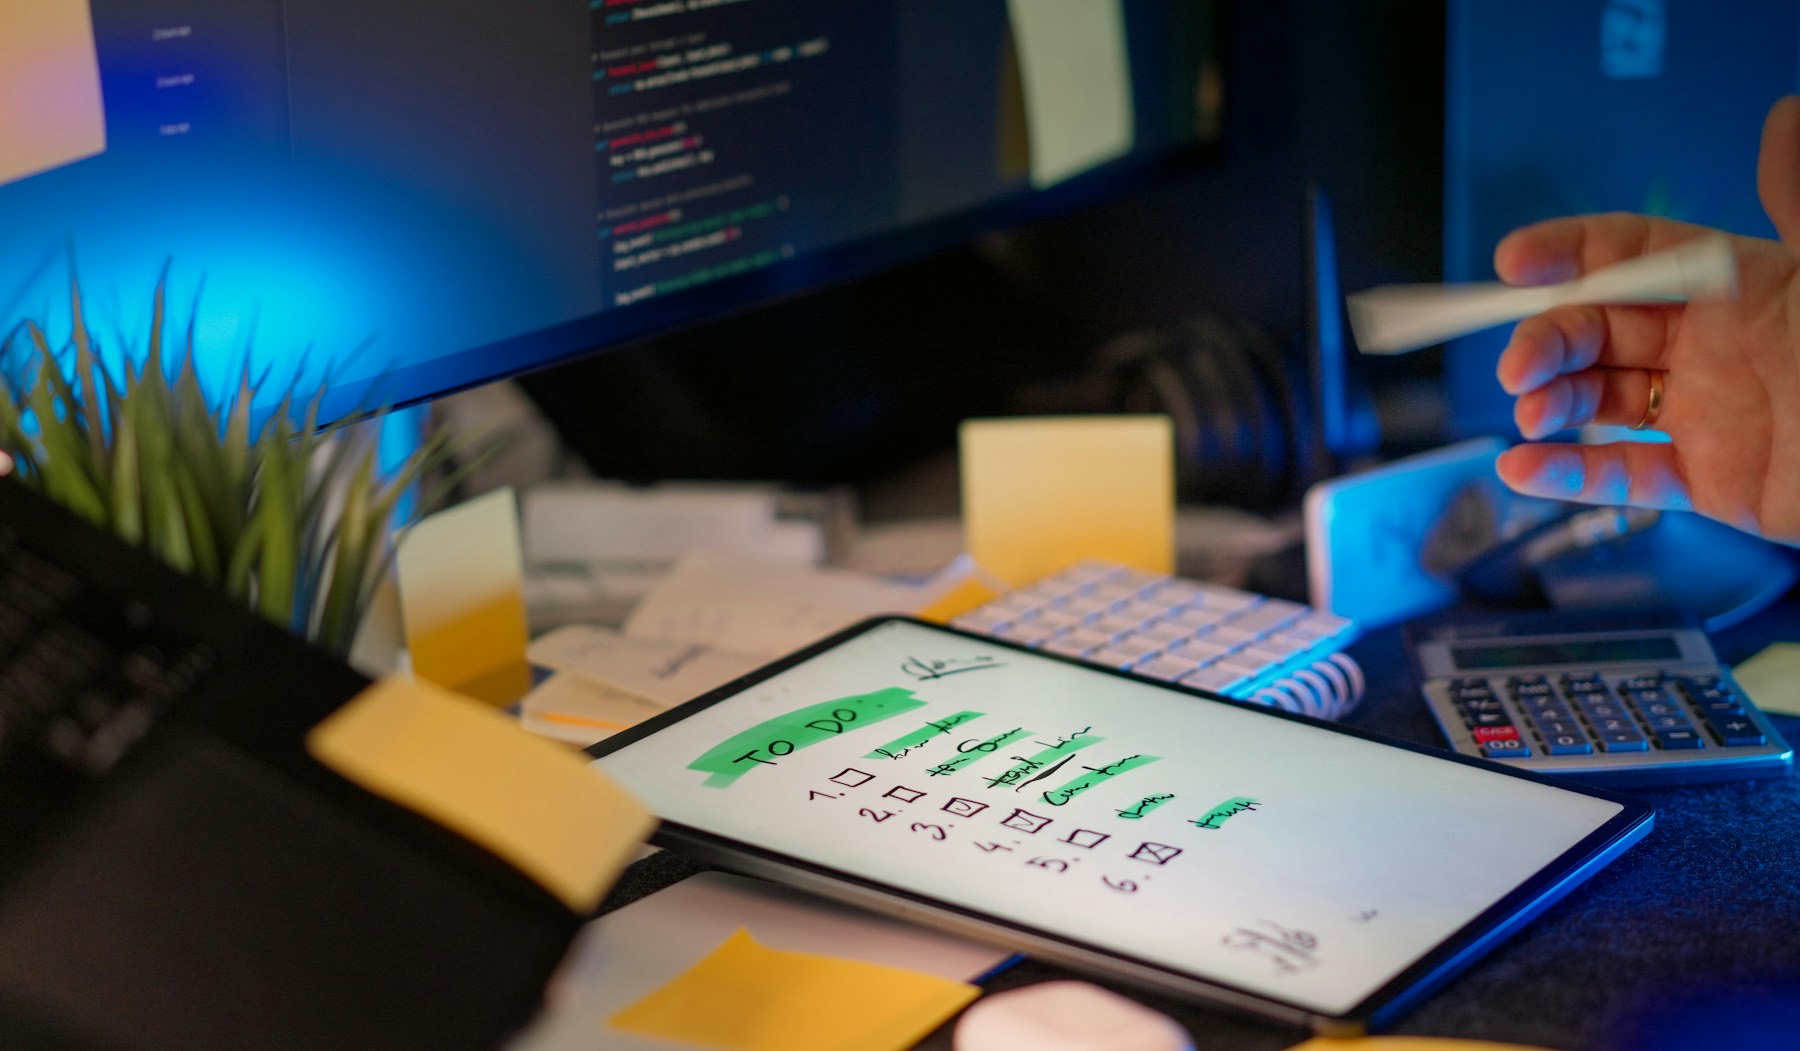
A desk at night: a monitor showing code, a tablet with a handwritten to-do list, sticky notes and a calculator
One order, by hand4 tools · 11 fields · about 6 minutes
Retyping per week in a 12-person operations team
4hdown from 46 h
Customer records that disagree between CRM and ERP
0.2%down from 7.1%
Nightly exports that failed last quarter with no alert
0down from 9

Illustrative Illustrative means example figures, not client results. We measure yours in week two.

$ how we use AI AI suggests · you approve

Every order checked before it reaches your ERP.

Pick which shop field fills each ERP field, or let AI suggest matches. We check each change against what the ERP accepts. Nothing the AI suggests is used until you approve it.

Try it: set total_amount → amount to Direct, and watch the check fail.

Interactive field mapper. Source fields from a shop order come first, then target fields of an ERP sales order. Select a source field, then a target field to link them. Pick a rule for each link, then review the checks and the test send below. Auto-map suggests links with a confidence score, for you to accept or reject. All data is fictional.

order-to-erpflow v3 · draft Valid · 10 mapped · 0 errors

Flow complete. Select any source field to change a mapping.

SourceStorefront · order.createdwebhook payload

TargetERP · POST /v2/sales-ordersJSON Schema 2020-12

Mappings10 of 10 targets

  1. id external_ref you
  2. created_at order_date you
  3. customer.email customer_id you
  4. customer.first_name customer_name you
  5. total_amount amount you
  6. currency currency_code you
  7. financial_status order_status you
  8. line_items[0].sku lines[].item_code you
  9. line_items[0].quantity lines[].quantity you
  10. shipping_address.city ship_to.city you

Previewsales_order.json

  1. {
  2. "external_ref": "ord_8F2K41",
  3. "order_date": "2026-09-14T16:17:03Z",
  4. "customer_id": "C-104233",
  5. "customer_name": "Asha Rao",
  6. "amount": 2499.00,
  7. "currency_code": "INR",
  8. "order_status": "INVOICED",
  9. "lines": [ {
  10. "item_code": "MUG-340-BLU",
  11. "quantity": 2
  12. } ],
  13. "ship_to": { "city": "Pune" }
  14. }

Validation8 / 8 required · 0 errors

  • external_refstring
  • order_datedate-time · UTC
  • customer_idmatches ^C-\d{6}$
  • customer_namestring · ≤ 80
  • amountmatches order lines · 2 × 1,249.50
  • currency_codeISO 4217
  • order_statusenum
  • lines[].item_codestring
  • lines[].quantityinteger ≥ 1
  • ship_to.citystring

Test deliverysandbox

POST /v2/sales-orders
Idempotency-Key: order.created:ord_8F2K41:r1
Authorization: Bearer •••• (scope sales_orders:write)

201 Created184 ms

{ "id": "SO-2026-004187", "status": "INVOICED" }

Created once. Sending the same order again returns this result, not a second order.

Fictional data Each order carries a unique key, so a retry cannot create a second order. Orders that still fail wait in a holding queue with the error attached. We send them again once fixed.

$ your options 4 methods · one set of alerts

Four ways to connect, chosen per link.

We choose by speed, volume, who owns the data and what happens when a system is down. All four share the same alerts.

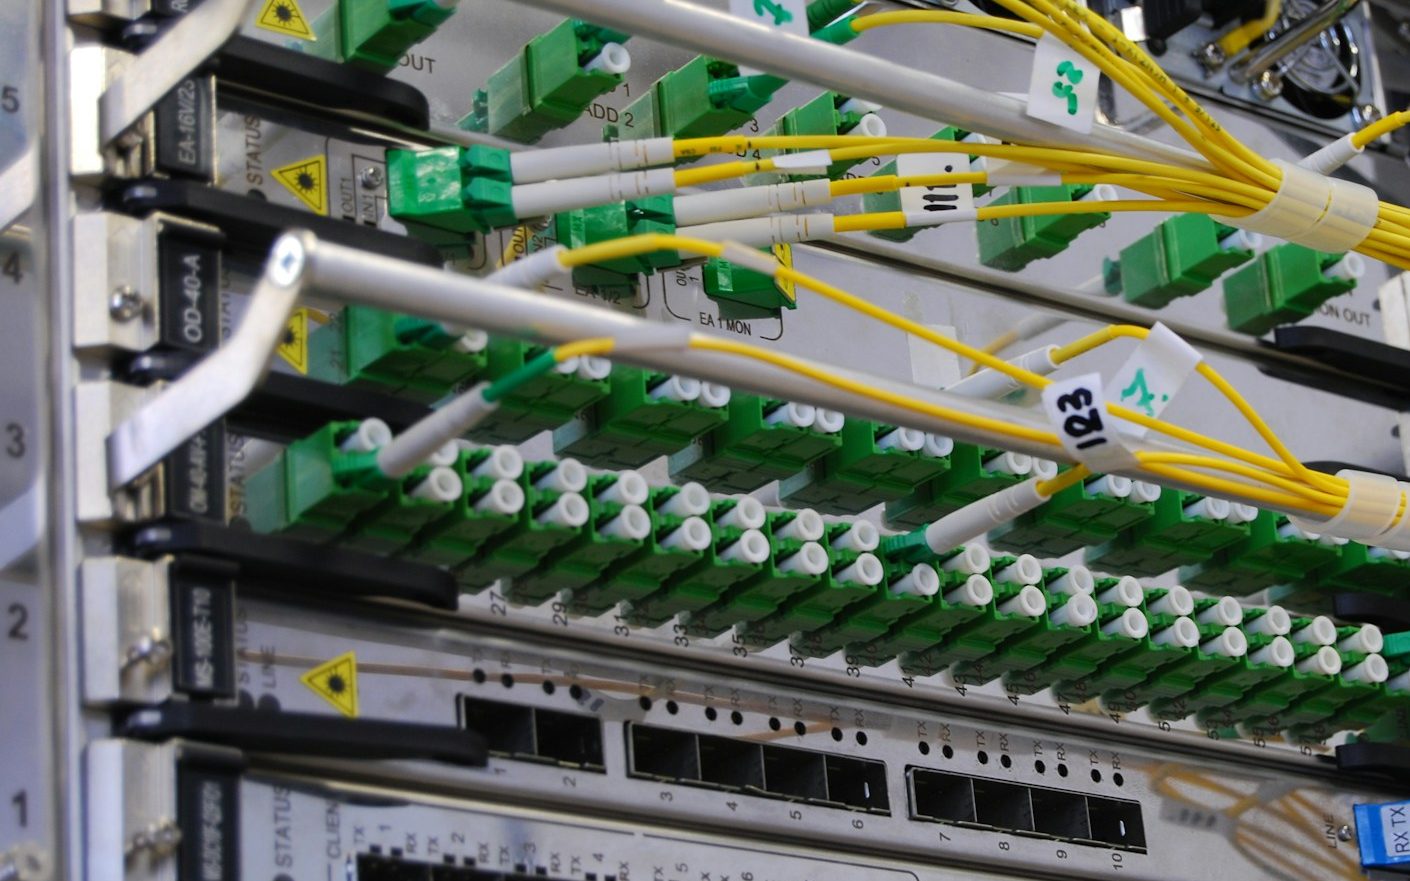
Close-up of network equipment: rows of green ports with yellow cables, each tagged with a handwritten number
Labelled at both ends every link named, owned and traceablePhoto: Kirill Sh / Unsplash
GET /v1/stock/MUG-340-BLU · checkout waits for the answer
  1. 200 GET /v1/stock/MUG-340-BLU · 212 ms
  2. 504 ERP timeout after 800 ms · retry 1 in 180 ms (backoff + jitter)
  3. 200 retry 1 succeeded · 246 ms · total 1.23 s

Ask and answer

One system asks another and waits for the answer. A front door checks who is asking and limits how often.

Use it when

  • A person is waiting: stock at checkout, a price, an account lookup.
  • The other system must confirm before the next step runs.
  • Volumes stay well within the supplier’s usage limits.

When it fails

  • Each request stops waiting before the caller’s own deadline.
  • Retries wait longer each time, and only for requests that are safe to repeat.
  • After repeated failures, calls pause and a saved answer is used. We respect each supplier’s limits.
  • Kong
  • GraphQL
  • OpenAPI Initiative
  • Postman
orders.v1 · one event, three consumers
  1. pub order.created ord_8F2K41 · written with the order, relayed from the outbox
  2. held CRM sync failed 5 attempts · 12 events held with errors
  3. resend 12 events resent after fix · 0 duplicates (unique keys)

Broadcast

The shop announces each order once. Every system that needs it listens, and the shop never waits for them.

Use it when

  • Several systems need the same update.
  • Busy spikes must not lose a single order.
  • One slow or broken system must not stop the rest.

When it fails

  • Each update is saved with its order in one step, then sent, so none go missing.
  • Every update arrives at least once, and repeats are ignored, so a resend changes nothing.
  • A shared rulebook blocks changes that would break other systems. Updates that keep failing wait in a holding queue.
  • Apache Kafka
  • RabbitMQ
  • Amazon EventBridge
  • Azure Service Bus
orders-db · polling off, log-based capture on
  1. u customers id=42 · tier silver → gold · LSN 0/16B37C8
  2. sink warehouse 1.4 s · search 0.6 s · cache key customer:42 dropped
  3. load source queries added by capture: 0

Copy each change

We read each saved change from the database’s own log and pass it on. Other systems stay current within seconds.

Use it when

  • An old or supplier database has no other way to connect.
  • Analytics and search must update within seconds of a change.
  • Repeated checks are already slowing the live database.

When it fails

  • It reads the database log, so the database itself does no extra work.
  • It starts from a full copy, then notes its place in the log, so restarts leave no gaps.
  • If the reader stalls, an alert fires before the database disk fills up.
  • Debezium
  • Apache Kafka
  • PostgreSQL
  • Snowflake
  • Elasticsearch
Support request intake · workflow v12
  1. #4811 5 steps · 1.8 s · succeeded
  2. #4812 create ticket 503 · retried in 30 s · succeeded
  3. #4813 new contact · lead created · 1.1 s

Connectors

Ready-made connectors and drag-and-drop steps, for flows that change often. Same alerts and change rules as everything else.

Use it when

  • Ready-made connectors exist for your tools.
  • Volumes are modest and your team wants to adjust the steps.
  • A fast first launch matters more than cost per run at high volume.

When it fails

  • Each step retries a set number of times, then alerts a named owner with the failed run.
  • Flows are saved with a full history and tested before going live.
  • Run history, alerts and dashboards sit beside the custom links.
  • n8n
  • Zapier
  • Make
  • MuleSoft
  • Boomi

Tools we work with, chosen per link. We do not claim partner status.

$ find your tool 31 tools · 9 categories

Tools we connect, and how they sync.

Search for a tool to see what we sync, how fast and what to watch for. Not listed? We connect any tool with public developer guides, or read its database.

31 of 31 tools

Commerce · connection details

Shopify

Direction
Two-way
Trigger
Webhooks
Freshness
Seconds

What typically syncs

  • Orders
  • Products
  • Inventory
  • Customers

How

  • Webhooks
  • GraphQL Admin API

Watch out for

Updates can arrive twice or out of order. We check each one’s signature, drop repeats and run a regular sweep for any that never arrived.
Tools we work with, shown with their own logos where allowed and a category icon where not. We claim no partner, certification or reseller status. Suppliers change their limits, so we check each one against its current guides when we build.

$ how we test rules first · old versions kept

Written rules that catch breaking changes early.

Both sides of each link test against the same written rules. A breaking change fails our checks before it reaches your customers.

Illustrative checks · fictional link

orders-api.yaml · OpenAPI 3.1 feat/customer-id
  1. @@ components.schemas.Order @@
  2. required:
  3. - id
  4. - order_date
  5. - customer_email
  6. - customer_id
  7. - amount
  8. properties:
  9. customer_email: { type: string, format: email }
  10. customer_id: { type: string, pattern: "^C-\d{6}$" }
  11. amount: { type: number, minimum: 0 }

Removing a required field is a breaking change. It goes out as a new version (v2). The old version keeps the old field for an agreed notice period.

Notice period, written into the change

  1. Week 0 v2.0.0 published v1 still sends customer_email. Both versions run side by side, both watched.
  2. Week 1 Teams notified Each team that uses it gets the change notes, updated code and a switch-over date it agrees to.
  3. Week 8 v1 retired v1 now replies with a link to the switch-over note. Nothing is removed while anyone still uses it.
contract-check · pull request #418 Blocked on v1 · goes out as v2.0.0
  1. Check the style

    Spectral style checks: names, error replies, paging and examples present.

    46 rules · 0 errors

  2. Detect breaking changes

    The new rules are checked against the live ones. A removed required field is flagged.

    1 breaking · order.customer_email removed

  3. Tests from each team

    Every team that uses the link runs its tests against the new version.

    2 of 3 tools fail

  4. Version & notice period

    Breaking change accepted as a new version, with the old field kept for one notice period.

    v2.0.0 proposed · needs sign-off

  5. Publish & notify

    The rules, change notes and updated code are published, and teams are notified.

    v2.0.0 published · 3 teams notified

Who is affected · from the register of tools3 registered
  • Warehouse dispatchLogistics Reads customer_email on every dispatch note. needs a change
  • Marketing syncGrowth Matches its mailing list by email address. needs a change
  • Finance exportFinance Uses id, order_date and amount only. unaffected
What we record
Each tool’s expected data, its owner and on-call contact
When tests run
On every change, and nightly on the supplier’s test system
What a failed test blocks
Only the change: v1 keeps working until notice ends
How a new tool joins
It adds its expected data from its own tests, with no ticket to raise
  • Passwords locked away

    Passwords and keys sit in a secure store, changed regularly, with limited access. Never in code or a notes field.

  • One key per link

    Each link gets its own key with the least access that works, so a leaked key cannot read everything.

  • Usage limits, both ways

    We respect the other side’s limits by slowing down, and publish our own so others can plan.

  • Tests from each team

    Teams that use a link record their own tests. We run them on every change to it.

Standards every link is written to

  • OpenAPI 3.1
  • AsyncAPI 3.0
  • CloudEvents 1.0
  • JSON Schema 2020-12
  • OAuth 2.1 · OIDC
  • Semantic Versioning 2.0

Security and privacy standards we build to

  • ISO/IEC 27001:2022Information security management systems
  • SOC 2Trust Services Criteria
  • GDPRGeneral Data Protection Regulation (EU) 2016/679
  • DPDP Act 2023Digital Personal Data Protection Act, 2023

The checks shown are illustrative. On a fictional orders link, a check finds a removed required field. It lists the two of three tools that would break. The fix is a new version with a notice period.

$ when a link fails Engineers on call

After launch, a named engineer answers.

Alerts fire on what your customers would notice. AI groups the errors and drafts the first update. The engineer checks it and makes every change.

Illustrative incident · fictional systems

INC-2026-0143 · severity 2

ERP order sync failing

Resolved · 41 minutes

  1. Alert: over 50 orders held System

    Orders have failed to reach the ERP for four minutes. The holding queue passes its limit and calls the on-call engineer.

    orders.erp.dlq · depth 52 · rising

  2. AI groups the failures AI

    The AI reads the error logs and finds one shared error. It links the matching fix guide and drafts the first update. It changes nothing.

    HTTP 400 · "material_code not found" · 52 of 52 · guide RB-014

  3. On-call engineer responds Engineer

    The engineer confirms the cause: a new shop product has no ERP product code. They correct the AI’s draft and send it.

    Answered 3 min · status updated

  4. Fix goes live Engineer

    Products without an ERP code now wait in a holding queue with the reason attached, instead of failing the whole batch.

    PR #1182 · deployed · behind a flag · queue steady at 63

  5. Held orders sent again System

    The 63 held orders are sent again in order. Unique keys stop any from creating a duplicate.

    63 resent · 0 duplicates · 0 held

  6. Incident review Engineer

    Written within two working days, with no blame, and every action owned and dated. This one added a daily check for missing ERP codes.

    PIR-2026-014 · 3 actions · 3 closed

AI drafts, groups and links. The engineer decides. Every action, the AI’s too, is recorded with its inputs, so the review uses the same record as everyone.

Held orders · count

0 now · peak 63

03:07resend03:52

  • 3min

    Time to respond

    Alert to a named engineer responding

  • 41min

    Time to fix

    Alert to the queue back at zero

  • 0

    Duplicate orders

    A unique key on every resend

  • 63

    Orders held, none lost

    Holding queue, resent in order

03:52IST

Our on-call engineer

23:22BST

Your team, asleep

An engineer working at a laptop in a dark office, screen light on their face

Each support agreement sets on-call hours and how serious each fault level is. The clocks show why every hand-off is written down.

Monitoring and on-call tools we use

  • OpenTelemetry
  • Grafana
  • Prometheus
  • Sentry
  • PagerDuty
  • Apache Kafka
  • Slack

An illustrative incident timeline. At 03:11, an alert fires when over fifty orders are held. AI groups the identical errors and links a fix guide. An engineer responds in three minutes and a fix goes live. The held orders are sent again with no duplicates. A review closes three actions. The chart shows held orders passing fifty at 03:11, peaking at 63 and back to zero after the resend.

$ plans 3 plans · 4 levels

Support plans, with targets in writing.

Three plans, from business hours to round the clock. Each sets how fast we answer and fix each fault level, plus monthly engineer hours for improvements.

Two engineers in glasses sit side by side watching a monitor closely in a dim, blue-lit room, one gesturing as he talks
On call response times set by fault levelPhoto: litoon dev / Unsplash

What each fault level means

  1. P1Critical

    A live link is down or sending wrong data. There is no workaround and the business stops.

    Orders stop reaching the ERP. Payments taken but not recorded.

  2. P2High

    A link is slow, late or partly failing, and someone is working around it by hand.

    The nightly stock sync fails for one warehouse. Support tickets sync late.

  3. P3Medium

    A small fault with limited effect: single records, one link or an error that blocks nothing.

    One customer record will not sync. Repeated retries clutter the log.

  4. P4Low

    A question, a small change or a planned improvement, done in the monthly engineer hours.

    Add a field to an existing link. Change when an alert fires.

Highlight a plan

Typical targets
Support plans compared: how fast we answer and fix each fault level, hours covered and monthly extras. Final targets are set in the signed agreement.
Commitment Essential Business hours, with monitoring and updates. Business Longer hours, with P1 call-out. Critical Round the clock, with an engineer on call.
Response
P1 · first response A named engineer replies in person. 4 business hours 1 hour 30 minutes
P1 · fix or workaround Working again, or a workaround agreed in writing. Next business day 8 business hours 4 hours
P2 · first response Checked, owner named, effect confirmed. 1 business day 4 business hours 1 hour
P2 · time to fix Link back to normal running. 3 business days 2 business days 8 hours
P3 · first response Logged, checked and added to the to-do list. 2 business days 1 business day 1 business day
P4 · first response Answered, or done in the monthly engineer hours. 5 business days 3 business days 2 business days
Coverage
Hours covered When the response clock is running. Mon–Fri · 09:00–18:00 IST Mon–Sat · 08:00–22:00 IST 24×7, every day
Out-of-hours call-out Which faults wake someone up. Not included P1 only P1 and P2
Named incident lead One person keeps you updated during a P1. Not included Included Included
Included
Engineer hours each month Improvements, upgrades and small features, ranked with you. 8 hours 24 hours 60 hours
Monitoring, security fixes & upgrades Alerts, security fixes and software updates for the links we run. Included Included Included
Service review Report on response times, incident reviews and the to-do list. Monthly report Monthly call Monthly call + quarterly plan

The same on every plan

  • Fault level is set by the effect on your business, and you can challenge it.
  • Every P1 gets a no-blame review afterwards, with actions tracked until closed.
  • Unused engineer hours are discussed at the monthly review, not quietly lost.
  • You can change plans at a service review, or cancel support with notice.

How we run support

Fault levels, incidents, problems and changes use ITIL 4 terms, the words your IT team already uses. We track our speed and stability with DORA metrics.

  • ISO 22301:2019Business continuity management systems
  • ISO 9001:2015Quality management systems
  • DORA metricsSoftware delivery performance

Standards we build our support to.

$ cost and energy 5 measures · one example

Fewer tools, fewer wasted checks.

A check every five minutes runs 288 times a day, even when nothing has changed. We send updates only when data changes, and retire tools that only move data.

tools.report one mid-size online shop Illustrative

After: links moved onto one connection hub, timed checks replaced where the supplier allows.

  • Software subscriptions

    Three tools existed only to move data between two others. Retiring them cuts their fees and the links to look after.

    26 seats

    was 34

  • Scheduled check jobs

    Most checks asked “has anything changed?” every five minutes and were told no. Updates sent on change replaced them.

    6 jobs

    was 41

  • Computing time used

    Idle checking jobs ran around the clock. The new links switch off between messages.

    430 hours / month

    was 1,240

  • Estimated energy

    Worked out from computing hours and the region’s published carbon figures, not measured at the socket.

    178 kWh / month

    was 512

  • Calls to supplier systems

    Fewer calls also means fewer usage-limit faults and lower supplier charges.

    0.4 million / month

    was 11.8

Four changes that cut cost and energy

Each is a normal choice when building links, and each cuts energy, licence fees and usage-limit faults.

  1. 01

    Send updates only on change

    If a supplier sends updates when data changes (webhooks), we use them. If not, we read just the changes from the database log.

    check every 5 min update only on change

  2. 02

    Run big syncs at quiet times

    The full check that both systems match runs nightly, when and where power is cleaner, not hourly.

    full check hourly, all day once nightly, on cleaner power

  3. 03

    Retire tools that only move data

    Once data flows through one connection hub you run, you can cancel tools that only linked two others.

    3 tools linking pairs 1 hub you already run

  4. 04

    Send less, less often

    We send only the fields needed, compressed. Grouping updates cuts the number of requests, without delaying urgent ones.

    whole record, every time changed fields, grouped

The panel shows one illustrative business before and after. Software subscriptions fall from 34 to 26 and scheduled checks from 41 to 6. Each month, computing time falls from 1,240 to 430 hours and estimated energy from 512 to 178 kWh. Monthly calls to supplier systems fall from 11.8 to 0.4 million.

$ how it works map · connect · go live · support

Four phases, from mapping to support.

We watch each link from the day it goes live, so the team that supports it already knows its history.

Typical phase lengths

Phase 01 / 04 Wk 01–02

Map

We map your tools, data, owners and weak spots. Then we agree how each link will work.

What this phase decides
Which links matter, and who decides when tools disagree.
What we need from you
Access to each tool in scope, and the person who owns it.

The phase is complete when

Every link has a named owner on your side and an agreed method on ours, signed off in writing.

What you keep

3
  • Connection map
  • Written data rules
  • Method per link

Who is involved

  • Systems architect
  • Your tool owners
  • Project lead

Where this phase usually slips

Ownership. Two teams each think they own the customer record. No link can be built until they agree which copy is right.

Phase 02 / 04 Wk 02–08

Connect

We build each link with retries, duplicate checks and alerts. We test it on safe test systems and recorded traffic.

What this phase decides
How each flow behaves when the other side is slow, down or wrong.
What we need from you
A test copy of each tool, and sample data that includes the awkward records.

The phase is complete when

Each link passes its tests on the supplier’s test system, and survives a planned failure with no data lost.

What you keep

3
  • Working links
  • Automatic tests
  • Alerts

Who is involved

  • Software engineers
  • Your IT team
  • Testers

Where this phase usually slips

Test systems. A supplier’s test system can differ from the live one. So we also test each link on recorded live traffic.

Phase 03 / 04 Wk 08–10

Go live

We write fix guides, agree access and your support plan, then rehearse an incident with your team.

What this phase decides
Who gets called, what they read first and what they may do.
What we need from you
An hour with whoever will take the calls, and where your alerts should go.

The phase is complete when

Your team and ours rehearse one full incident using the live fix guide and alert.

What you keep

3
  • Fix guides
  • Support plan
  • Practice incident

Who is involved

  • Reliability engineer
  • Your on-call rota
  • Service manager

Where this phase usually slips

The rota. Alerts to a shared inbox are not on-call cover. This phase stays open until a named person gets the alert.

Phase 04 / 04 Ongoing

Support

We stay on call, fix faults, upgrade and improve. You get a monthly review and a plan each quarter.

What this phase decides
What to improve next, and which changes are worth making.
What we need from you
Thirty minutes a month for the service review.

The phase is complete when

It does not close. Support is reviewed every month against the same measures.

What you keep

3
  • Monthly reports
  • Incident reviews
  • The plan

Who is involved

  • Named incident lead
  • Service manager
  • Your product owner

Where this phase usually slips

Silence. A quarter with no reported incidents usually means the monitoring has gaps.

Support starts in phase three, so there is no hand-off at the end.

The four phases in order: Map (Wk 01–02), Connect (Wk 02–08), Go live (Wk 08–10), Support (Ongoing). Each panel shows what the phase decides and what we need from you. It also shows when it is done, what you keep, who is involved and where it often slips.

$ what you get 7 items · in your own accounts

Seven things you keep and what they do.

Maps, link documents, code, tests, fix guides and reports, so your team or a new supplier can run your links.

  1. 01

    Map of your tools and data flows

    Every tool and link, where each field’s master copy lives and who owns it. A new engineer reads it first.

    Diagrams

  2. 02

    Link documentation for developers

    Standard link documents (OpenAPI 3.1, AsyncAPI), kept with your code and published for your teams and suppliers.

    OpenAPI · portal

  3. 03

    Working links with alerts

    The link code, stored in your own accounts with its dashboards and alert rules.

    Code · tools · alerts

  4. 04

    Automatic tests for every link

    Tests from each team that uses a link, run on every change. A supplier’s change fails a test, not a customer order.

    Auto-run tests

  5. 05

    Support plan and response times

    Fault levels, response and fix times, who to call next and named contacts, agreed before launch.

    Agreement

  6. 06

    Fix guides & on-call rota

    One page per fault: what the alert means, how to fix it and when to get help.

    Docs · rota

  7. 07

    Monthly service report

    Sync success, how fresh the data is, incidents, what we changed and the to-do list for next month.

    Report

  8. Who owns the work

    What we make for you is yours once it is paid for. Tools we already had stay ours, and you get a free, permanent licence to use them.

    Start a project

Code in your own accounts

Link code, server set-up files, tests and alert rules go into code accounts you own from the first week.

Keys stay in your secure store

Supplier keys and logins are created in your accounts. Our access is limited, and you can remove it in one step.

Documented for handover

Fix guides, decision notes and the connection map are updated as links change, so another team can take over support.

$ how we report same seven measures, every month

Measures we report monthly, in writing.

Every monthly review reports these seven measures. Each shows how it is worked out and where the data comes from, so months compare easily.

  1. 01

    Sync success rate

    The share of updates the receiving tool accepts, counted after retries.

    Read from Receipts from each tool · OpenTelemetry

    Typical when we start

    96.4%

    Target

    99.9%

    96% of the way to target by the third review

  2. 02

    Data freshness

    How long a change takes to reach the other tool. 95% of the month’s updates arrive within this time.

    Read from Times recorded at both ends

    Nightly copy

    6 h

    Target

    5 min

    74% of the way to target by the third review

  3. 03

    Updates in the holding queue

    Failed updates still waiting after every retry, counted at day end. Anything older than 24 hours is passed up for action.

    Read from Queue size, with an end-of-day alert

    Before monitoring

    180

    Target

    0

    88% of the way to target by the third review

  4. 04

    Manual steps removed

    Records once retyped or copied by hand each week that a link now handles.

    Read from Counted with your team in the list of links

    At the start

    0

    After phase two

    400

    62% of the way to target by the third review

  5. 05

    Time to respond (MTTA)

    Average time from an alert to a named engineer responding, for P1 faults only.

    Read from On-call tool · incident log

    No monitoring

    42 min

    Target

    15 min

    55% of the way to target by the third review

  6. 06

    Time to fix (MTTR)

    Average time from an alert until it works again, for P1 faults only. A lasting fix to the cause may come later.

    Read from Incident log · DORA metrics

    No monitoring

    7 h

    Target

    2 h

    70% of the way to target by the third review

  7. 07

    Unneeded subscriptions cancelled

    Tools that only moved data between two others, cancelled once your links run on systems you already run. Timed checks are counted separately.

    Read from Your licence list · list of timed jobs

    At the start

    0

    Year one

    8

    45% of the way to target by the third review

Illustrative

Starting points are typical for tools with no monitoring. They show the shape of the change, not a promise about yours. The progress figure is where a typical setup sits by the third monthly review. Targets are set per link when we start, written into the support agreement and reviewed if volumes change.

  • Monthly service review Thirty minutes with your team: the seven measures, every incident and what we propose to change next.
  • Missed target A missed target is written up in the same report, with the cause and the fix, before the next month starts.
  • Your copy of the data Dashboards sit in your monitoring tools, so you can check the same numbers on any day.

Seven measures are reported each month. Sync success, targeted at 99.9 per cent. Data freshness, from a nightly copy to five minutes for 95% of updates. Holding queue size, down to zero. Manual steps removed, around four hundred a week after phase two. Time to respond to a P1 alert, targeted at fifteen minutes. Time to fix, targeted at two hours. Unneeded subscriptions cancelled in the first year. Each row also shows how far a typical setup has moved towards its target by the third monthly review. All figures are illustrative.

Offers & plans

Connect your tools so data flows between them.

We connect your tools so data is typed once and matches everywhere. After launch, the engineers who built your links watch them, fix faults and keep them up to date.

Categories
04
Offers
16
Plans
04
Not sure what you need? Tell us the problem

How to buy

  1. 01Pick offers. Ask about one, or add several to one enquiry.
  2. 02Choose a plan. A small job, a fixed project or ongoing help.
  3. 03Send your enquiry. We reply within one working day.

Browse by category

Timelines are typical. We write the scope before we quote.

01Connecting tools

5 offers
Typical timeline: 3–8 weeks

Links between your tools

Connect two or more tools so data moves between them by itself, with retries, alerts and no duplicates.

What’s included

  • Connection map and data rules
  • Retries, duplicate checks and holding queues
  • Tests on suppliers’ test systems
  • Monitoring and alerts
  • Type once
  • No duplicates
  • Monitored

Best forTeams typing the same data into several tools.

Typical timeline: 4–10 weeks

CRM & ERP links

Link your CRM, ERP, accounting and marketing tools so customers, orders and invoices stay in step everywhere.

What’s included

  • Salesforce, HubSpot, Zoho or SAP connectors
  • Field matching and ownership rules
  • Two-way sync with conflict handling
  • Checks that records match
  • Salesforce
  • HubSpot
  • SAP
  • Salesforce

Best forSales and finance teams working from different numbers.

Typical timeline: 2–6 weeks

Online payments

Take payments online, in your app or by subscription, with refunds and payment matching included.

What’s included

  • Razorpay, Stripe or PayPal set-up
  • UPI, cards, subscriptions and refunds
  • Payment updates checked for tampering
  • Payouts matched to orders
  • Razorpay
  • Stripe
  • UPI

Best forBusinesses adding or changing how they take payments.

Typical timeline: 2–5 weeks

Automatic messages

Send order updates, one-time passwords, reminders and alerts by SMS, WhatsApp, email or Slack straight from your tools.

What’s included

  • WhatsApp Business, SMS and email connected
  • Message templates and opt-outs
  • Message tracking
  • Backup channel if one fails
  • WhatsApp
  • SMS
  • Email
  • Twilio
  • Slack
  • Microsoft Teams

Best forBusinesses that need to reach customers or staff automatically.

Typical timeline: 4–8 weeks

Partner & app links

Documented links your partners and apps can build on, with security, usage limits and usage reports.

What’s included

  • Link rules written before code
  • Log-ins and usage limits
  • Documentation site for developers
  • Version and notice-period rules
  • OpenAPI
  • Secure access
  • Usage limits

Best forCompanies opening their software to partners or building mobile apps.

02Ready-made & instant links

3 offers
Typical timeline: 3–8 weeks

Ready-made connectors

Ready-made flows on MuleSoft, n8n, Make or Zapier that your team can read and change, watched like custom code.

What’s included

  • Tool chosen for cost and volume
  • Flows with error handling and alerts
  • Safe testing before changes go live
  • Team training and documentation
  • Ready-made
  • Tracked changes
  • Team-editable
  • MuleSoft

Best forTeams whose tools have ready-made connectors and modest data volumes.

Typical timeline: 6–12 weeks

Broadcast updates

One tool announces a change, such as a paid order, and others react at once. New tools join without rewiring the rest.

What’s included

  • Message design and data rules
  • Kafka or RabbitMQ set-up
  • Copying each change from databases
  • Holding queue and resending
  • Events
  • Kafka
  • CDC

Best forBusinesses with many tools where direct links break easily.

Typical timeline: 2–4 weeks

Link check & repair

Fix links that fail silently, make duplicates or need clean-up by hand, then add the monitoring they lack.

What’s included

  • Review of links and past failures
  • Root-cause fixes
  • Monitoring and alerts
  • Fix guide for each link
  • Rescue
  • Root cause
  • Monitoring

Best forTeams matching up data by hand every week.

03Syncing & moving data

3 offers
Typical timeline: 3–8 weeks

Data sync between tools

Keep records matching across tools, almost instantly, with clear rules on which tool owns each field.

What’s included

  • Master-copy rules per field
  • Near-instant sync
  • Conflict detection
  • Daily check that records match
  • Sync
  • Ownership rules
  • Matched

Best forBusinesses running more than one tool for customers, products or stock.

Typical timeline: 4–12 weeks

Switching systems

Move from one CRM, ERP, online shop or helpdesk to another, with every record accounted for.

What’s included

  • Matching and clean-up rules
  • Full practice runs first
  • Checks: record counts and field samples
  • Switch-over with a way back
  • Rehearsed
  • Matched
  • Way-back plan
  • Salesforce

Best forCompanies switching a core system.

Typical timeline: 4–10 weeks

Connecting old systems

Put a new link in front of an old system. New tools use it safely while you plan its replacement.

What’s included

  • Link layer over the old system
  • Caching and usage limits
  • Monitoring
  • Piece-by-piece replacement plan
  • Link layer
  • Strangler pattern

Best forOrganisations with a system that is hard to change but still essential.

04Support after launch

5 offers
Typical timeline: Set-up 2–4 weeks, then monthly

Managed support with SLAs

Engineers watch your tools, answer faults within agreed response times (SLAs) and keep you informed, with a monthly review.

What’s included

  • Response and fix times by level
  • Monitoring and alerts
  • Incident handling and no-blame reviews
  • Monthly service report
  • SLA
  • On-call
  • Monthly review

Best forBusinesses whose key systems cannot go unsupported.

Typical timeline: Set-up 2–4 weeks, then monthly

Back-up for your helpdesk

Engineers behind your helpdesk who look into bugs, fix code and sort out data problems your first-line team cannot.

What’s included

  • Ticket intake from your helpdesk
  • Finding the cause and fixing code
  • Help articles for your first-line team
  • Clear hand-offs and monthly reports
  • L2
  • L3
  • Root cause

Best forProduct companies whose developers keep being pulled into support.

Typical timeline: 1–3 weeks to set up, then monthly

Outage & speed monitoring

Automatic checks on your websites and links, with alerts sent to the right person when something fails.

What’s included

  • Online checks and scripted test visits
  • Error and speed tracking
  • Alerts to the right person
  • Public or internal status page
  • Journey checks
  • Alerts
  • Status page

Best forAny business that earns money online.

Typical timeline: Ongoing, monthly

Monthly improvements

Set engineer hours each month for upgrades, security fixes, speed and the small features that pile up.

What’s included

  • Agreed hours each month
  • Software and security updates
  • To-do list ranked with you
  • Quarterly plan review
  • Retainer
  • Upgrades
  • Planning

Best forTeams with a steady stream of small changes and no spare developers.

Typical timeline: 3–6 weeks

Taking over support

We take over support for systems we did not build. First we check the code, servers and documents, so response times are realistic.

What’s included

  • Initial review
  • Gaps fixed before support starts
  • Fix guides and access set-up
  • Handover from the previous team
  • Takeover
  • Review first
  • Handover

Best forFirms changing supplier or losing the original developers.

Your enquiry

Tick “Add to enquiry” on any offer, choose a plan, then continue. Or enquire about one offer.

How we work with you

Ways to start, from a question to a quote.

Ask a quick question, send your project details or request a quote. The person who will lead the work reads each one in full. Services in your enquiry go with it.

Or book a 30-minute call

What are you sending?

  1. 01

    About 2 minutes3 short answers

    For a first chat, a press request or anything not ready to plan yet.

    You get A reply from a named lead

  2. 02Recommended

    About 8 minutes5 short steps

    Goals, who it is for, budget and timing, so our first reply can outline the work.

    You get Options and prices after one call

  3. 03

    About 15 minutesYour documents attached

    Your documents, deadlines and the purchasing and security rules to meet.

    You get Confirmation and a named lead

How it is priced

Each plan shows how it is priced. Work starts once we agree a written scope and price.

  • Typical length
    4–12 weeks
    Pricing
    Fixed price
  • Typical length
    Ongoing · 6-month minimum
    Pricing
    Monthly fee
  • Typical length
    3–9 months
    Pricing
    Fixed price per stage
  • Typical length
    6–18 months
    Pricing
    Priced per written scope
Compare what each plan includes
What each plan includes and who it suits
PlanWhat you getBest for
ProjectOne clear job for one fixed price.
  • A written scope: what you get and how we agree it is done
  • A named project lead and a fixed team
  • A shared plan with checkpoint dates
  • Source files, yours once paid for
A brand identity, a website, a simple app or a set of tools
RetainerA monthly team that runs and improves what we built.
  • Team time set aside for you every month
  • Agreed response times for requests and fixes
  • A monthly review and a to-do list
  • Planned improvements, not only fixes
Monthly social media and ads, or care for live sites and apps
MilestoneA bigger build in stages you approve and pay for one at a time.
  • Stages, each with its own scope and approval
  • A go or stop review at each stage
  • Re-plan between stages as you learn
  • Pay for each stage you approve
Work too big for one contract, such as a large app
EnterpriseA large, long project with its own team and agreed response times.
  • A project director and a decision group
  • A team for each part of the work
  • Response times, reports and a list of risks
  • Security, legal and purchasing checks in the plan
Large companies making changes across markets, brands or business units

$ questions seven common questions

Links and support, your questions answered.

Seven questions teams ask before we connect their tools. If yours is missing, add it to your enquiry. We will answer in writing before we discuss price.

01 Connectors or custom code? Approach

Often both, chosen per link, with the same alerts. Ready-made connectors in Zapier, Make or n8n suit standard links and teams who edit flows themselves. Custom code suits high volumes, complex data or strict speed needs.

02 What response times do you offer? Response times

They depend on your plan and the fault level. We agree them per system in writing, with the hours we cover and your monthly engineer hours.

03 Can you support systems you did not build? Taking over

Yes, after we check the code, servers, alerts and documents. We fix gaps first, so our response times are realistic.

04 What if something breaks? Incidents

An engineer responds within your plan’s agreed time. If your plan includes one, a named lead updates you during a P1. Every P1 gets a no-blame review.

05 What does monthly support include? Retainer

Monitoring, incident response, security fixes and software updates. It also includes set engineer hours each month for improvements you choose with us.

06 What if a supplier changes their system? Change

Tests catch it, and we update the link before their deadline. With no warning, failed updates wait in the holding queue until fixed, so nothing is lost.

07 Can we end the support agreement? Exit

Yes, with the notice period in your contract. Support runs on a rolling term. Your code, tests, fix guides and keys stay in your accounts, so a handover is planned work.

Tell us what you need built.

You will talk to the lead who would run your work.

Book a call

Three ways to start

We always agree a written scope and price before work begins.

Choose one of the three ways above