Capability 01 / 04 · Interfaces for systems that guess

The model is probabilistic. The experience cannot be.

AI Application Design shapes what an AI product feels like to use: assistants, agentic flows and multimodal interfaces designed across Gemini, OpenAI, Anthropic and open-weight models. Every screen accounts for the uncertain answer, the slow answer and the wrong one.

Typical length
6–12 weeks to a working prototype
Surfaces
Chat · voice · vision · agentic
Standard
Tested against a prompt set

Illustration: an assistant conversation. A user asks which enterprise contracts renew before March and whether pricing terms changed. The assistant shows a read-only plan of three tool calls, answers with three numbered citations, says two scanned contracts could not be read, and proposes drafting reminders to three account owners, which waits for the user to approve.

What it covers

Six design problems every AI product has

Each one is a decision about control: what the system does on its own, what it asks for, and what it shows so a person can tell whether to trust it.

  1. 01 / 06

    Conversation & prompt design

    The first message, the questions it asks, the refusals and the recovery. Written as a script and tested with real users before it reaches a model.

    Scripted · tested

  2. 02 / 06

    Agentic interaction patterns

    How a plan is shown, paused, edited and approved. The user sees each step, keeps the stop button and can undo what the agent did.

    Plan · approve · undo

  3. 03 / 06

    Multimodal interfaces

    Voice, camera, document and screen input designed together, with a clear hand-back to typing when the room is loud or the light is poor.

    Voice · vision · document

  4. 04 / 06

    Trust & transparency surfaces

    Citations, sources, confidence, edit history and a plain account of what the system used. Designed so people check rather than assume.

    Cited · inspectable

  5. 05 / 06

    Latency, failure & fallback design

    Streaming, progressive disclosure, partial results and honest empty states. What the interface does at four seconds, and what it does when the model is wrong.

    Streaming · graceful failure

  6. 06 / 06

    Experience evaluation

    Task-based testing with real users against a fixed set of prompts and edge cases, scored for completion, correction effort and trust.

    Task success · trust

How it runs

A prototype in weeks, tested on real prompts

A working prototype on a live model, early. Paper cannot tell you how a probabilistic system feels. Timings are typical, set per engagement.

  1. Wk 01–02

    Frame

    Users, jobs to be done, the data the system may see and the actions it may take. Failure modes named before features.

    • Experience brief
    • Capability & risk map
    • Prompt set v1
  2. Wk 02–06

    Design

    Flows, conversation scripts and interface design built in the design system, prototyped against a live model rather than a static mock.

    • Interaction design
    • Conversation scripts
    • Live prototype
  3. Wk 05–09

    Test

    Task-based sessions with real users on real prompts, including the cases where the model is wrong. The design changes on what they do, not on what they say.

    • Usability findings
    • Revised flows
    • Prompt set v2
  4. Wk 09–12

    Hand over

    Specifications, tokens and components handed to engineering, with the prompt set and the acceptance criteria attached.

    • Design specification
    • Components
    • Acceptance criteria

In practice · failure-state catalogue

Designed for the wrong answer as carefully as the right one.

Every way the assistant can fail gets a designed state: what triggers it, what the person sees, how they recover, and the test that proves it on the live model.

Failure states · Support assistant5 of 23 states
Failure states · Support assistant: illustrative sample
StateTriggerWhat the person seesRecoveryTested
No source found Retrieval under thresholdSays so, offers searchOne tap to a person41 / 41
Low confidence Grader score < 0.7Answer with caveat + sourcesAsk a follow-up38 / 40
Action needs approval Refund over limitPlan shown, approve or editNamed approver25 / 25
Prompt injection attempt Instruction in a documentIgnores it, flags the fileLogged for review18 / 20
Out of scope Legal or medical askDeclines, explains whyHand-off with context9 / 12
States designed
23Before launch, not after
Prompt-set pass rate
94%Target 95% to ship
Hand-offs with context
100%No repeat questions

Illustrative Taken from a prototype. Your catalogue is written against your own prompt set and policies.

What changes

People trust it because it shows its working.

Three measures taken on the live-model prototype, baselined before design starts. Typical targets, not promises; yours are set per engagement.

01

Designed for the wrong answer

Every screen has a state for uncertain, slow and incorrect. People recover from a bad answer instead of losing trust in the product.

Recovery after a wrong answer

  • Before35%
  • Target80%+

Measured by Moderated sessions on the prompt set

02

Control people can feel

Plans are visible, consequential actions are approved, and anything the system did can be undone.

Agent actions approved first time

  • Before50%
  • Target85%+

Measured by Approval events in the prototype log

03

Evidence before engineering

Decisions tested with real users on a live model, so the build starts from what already worked.

Task success on the prompt set

  • Before58%
  • Target85%+

Measured by Tasks completed ÷ tasks attempted

What you keep

The specification engineering builds to, in your repositories.

Conversation design, the failure-state catalogue, the prompt set and the tested prototype live in your repositories and design files from the first week.
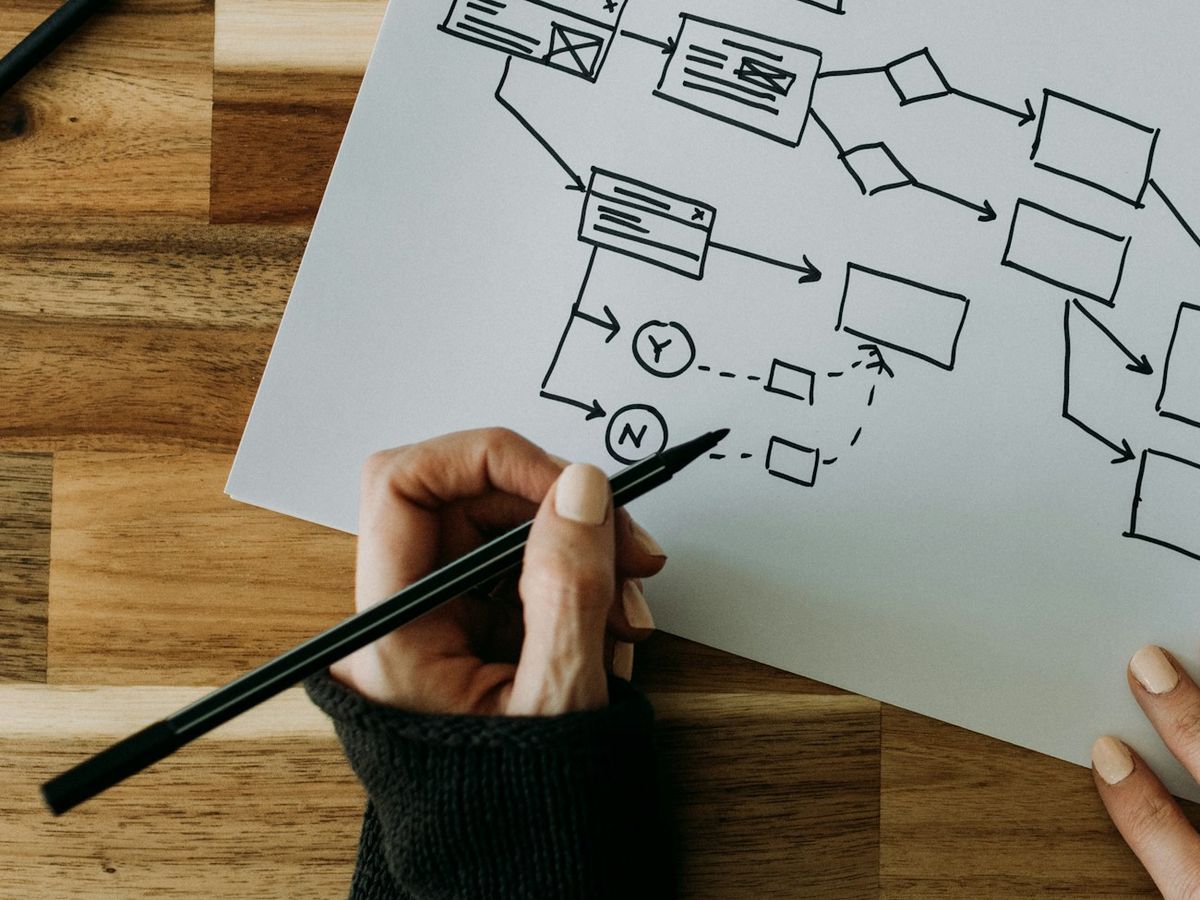
A hand sketches a flow diagram on paper, the pen resting on a yes-or-no branch
Every branch drawnthe wrong answer included

Manifest · AI Apps7 items

AI Application Design deliverables and their formats
#DeliverableFormat
01AI experience brief & capability mapDoc · board
02Interaction design & flowsFigma
03Conversation & prompt scriptsDoc · prompt set
04Working prototype on a live modelPrototype · repo
05AI interface pattern libraryFigma · Storybook
06Experience evaluation reportReport · recordings
07Design specification & acceptance criteriaDoc · tickets

Where it sits

Design sets the bar. Engineering clears it.

AI Application Design owns what people meet. The acceptance criteria it writes become the tests engineering builds against.

  1. AI Design AI Strategy & Consulting

    Which use case, and why this one first.

  2. AI Design · this page AI Application Design

    The conversation, controls and failure states, tested on a live model.

  3. Technology & Intelligence AI engineering

    Agents, retrieval and infrastructure built to the specification.

  4. Both Production evaluation

    The same prompt set, re-run on every release.

The prompt set written in week one is the thread through all four.

Technologies we work with

Designed on a live model, never a mock-up of one.

The design, model and prototyping tools AI application work runs on, most used first. Chosen on your prompt set; nothing locks you to a vendor.

  • Figma
  • Anthropic
  • Google Gemini
  • Mistral AI
  • LangGraph
  • TypeScript
  • React
  • Next.js
  • Storybook
  • Vercel
  • PostHog

Also in use

  • OpenAI
  • LlamaIndex
  • Playwright

Frameworks we build to

Safe to put in front of people and ready for your reviewers.

The frameworks that shape the guardrails, the failure states and the records we hand over. We build to them; they are not certifications we hold.

  • WCAG 2.2 AAWeb Content Accessibility Guidelines

    Perceivable, operable, understandable and robust content, including 2.2 criteria such as focus not obscured, target size and accessible authentication.

  • EU AI ActArtificial Intelligence Act (EU) 2024/1689

    A risk-based regime: prohibited practices, obligations for high-risk systems, transparency duties and rules for general-purpose AI models.

  • NIST AI RMF 1.0AI Risk Management Framework

    Four functions for trustworthy AI: Govern, Map, Measure and Manage, with a companion profile for generative AI (NIST AI 600-1).

  • OWASP Top 10 for LLM ApplicationsLLM and generative AI security risks

    Risks specific to LLM systems, including prompt injection (LLM01), sensitive information disclosure (LLM02), excessive agency (LLM06) and vector and embedding weaknesses (LLM08).

  • GDPRGeneral Data Protection Regulation (EU) 2016/679

    Lawful basis, data-subject rights, data protection by design and by default, breach notification and DPIAs for high-risk processing.

  • DPDP Act 2023Digital Personal Data Protection Act, 2023

    Notice and consent, duties of data fiduciaries, rights of data principals, breach intimation and added duties for significant data fiduciaries, with the DPDP Rules.

Services & packages

Design the experience first. The model is only the engine.

Buy the design of one AI surface, such as an assistant, an agentic flow or a voice interface, or the whole experience from concept through to a specification your engineers can build. Everything is prototyped on a live model and tested with real users.

Categories
04
Services
14
Packages
04
Not sure what you need? Describe the problem

How to buy

  1. 01Pick services. Enquire about one, or add several to a brief.
  2. 02Choose how to engage. A sprint, a fixed project or an ongoing team.
  3. 03Send the brief. We reply within one working day.

Browse by category

Timelines are typical. Every quote follows a written scope.

01Discovery & concept

3 services
Typical timeline: 2–3 weeks

AI experience diagnostic

A review of an AI feature you have already shipped: where people abandon it, where they stop trusting it and what to change first.

What’s included

  • Session and transcript review
  • Heuristic review against AI interface patterns
  • User interviews with people who stopped using it
  • Ranked list of fixes with effort
  • Entry point
  • Diagnostic
  • Ranked fixes

Best forTeams with an AI feature live and usage that is quietly falling.

Typical timeline: 2 weeks

AI concept sprint

Two weeks to turn an ambition into three concrete concepts, each one demoed on a real model so the choice is made on behaviour rather than on a slide.

What’s included

  • Framing session with your team
  • Three concepts designed and demoed
  • Feasibility, cost and risk read on each
  • Recommendation and next steps
  • Sprint
  • Demos
  • Decision
  • OpenAI

Best forLeadership teams choosing between several AI ideas.

Typical timeline: 3–5 weeks

AI product definition & service blueprint

What the product does, what it refuses to do, where a person stays in the loop, and how the work flows behind the interface.

What’s included

  • Jobs, users and failure modes
  • Capability and boundary definition
  • Service blueprint including the human steps
  • Success measures and acceptance criteria
  • Definition
  • Blueprint
  • Boundaries

Best forTeams whose AI product scope changes in every meeting.

02Interaction design

4 services
Typical timeline: 3–6 weeks

Conversation & prompt design

The words the system uses: its opening, its questions, its refusals and its recovery, written as a script and tested before a model is wired in.

What’s included

  • Conversation scripts for the main journeys
  • System prompt and tone specification
  • Refusal, repair and escalation wording
  • Script testing with real users
  • Scripts
  • Tone
  • Refusals
  • OpenAI

Best forAssistants and chat products where the writing is the interface.

Typical timeline: 4–8 weeks

Agentic interaction design

How a plan is shown, paused, edited and approved, so people can see what the software intends before it acts and undo it afterwards.

What’s included

  • Plan preview and step-through design
  • Approval, permission and spend-limit patterns
  • Interruption, retry and undo states
  • Audit view of what the agent did
  • Agents
  • Approval
  • Undo

Best forProducts where software acts on a customer’s or colleague’s behalf.

Typical timeline: 4–8 weeks

Multimodal & voice interface design

Speech, camera and document input designed alongside typing, with confirmation and repair flows for the times the input is imperfect.

What’s included

  • Voice and camera interaction design
  • Confirmation, barge-in and repair flows
  • Typed equivalent for every spoken step
  • Noise, lighting and low-quality input states
  • Voice
  • Camera
  • Repair flows
  • OpenAI

Best forProducts used hands-free, in the field or on a phone camera.

Typical timeline: 3–5 weeks

Trust, citation & control design

The parts of the interface that let someone judge an answer: sources, what the system used, what it is unsure about, and how to correct it.

What’s included

  • Citation and source-inspection patterns
  • Uncertainty and confidence presentation
  • Correction, feedback and override flows
  • Disclosure of AI involvement per surface
  • Citations
  • Uncertainty
  • Override

Best forProducts used for decisions where a wrong answer has consequences.

03Systems & build

3 services
Typical timeline: 6–10 weeks

AI interface design system

The reusable parts of an AI interface — streaming text, citations, plan steps, approvals, empty and error states — designed once and documented in code.

What’s included

  • Component set with tokens
  • Streaming, loading and partial-result states
  • Accessibility behaviour per component
  • Documentation in Storybook
  • Design system
  • Components
  • Documented

Best forOrganisations adding AI to several products and repeating the same work.

Typical timeline: 4–8 weeks

Working prototype build

A prototype on a live model with your own content, built to be tested with users, shown to a board or taken into a funding conversation.

What’s included

  • Prototype on your data or a safe sample
  • Retrieval or tool calls where the concept needs them
  • A fixed prompt set covering the awkward cases
  • Test sessions and a findings report
  • Prototype
  • Live model
  • Testable
  • LlamaIndex

Best forTeams that need evidence before committing an engineering budget.

Typical timeline: Ongoing, by sprint

Design support through the build

Designers embedded with your engineers through delivery, answering the questions a specification cannot, and reviewing what ships against what was agreed.

What’s included

  • Designer in your sprints and reviews
  • Specification updates as the model behaves
  • Design QA against acceptance criteria
  • Accessibility checks before release
  • Embedded
  • Design QA
  • Your cadence

Best forEngineering teams building an AI product without a designer who knows the territory.

04Evaluate & operate

4 services
Typical timeline: 3–5 weeks

Experience evaluation with real users

Task-based sessions on a fixed prompt set, including the cases where the model is wrong, scored for completion, correction effort and trust.

What’s included

  • Prompt set covering the awkward cases
  • Moderated sessions with real users
  • Scoring for completion, effort and trust
  • Ranked findings with design changes
  • Usability
  • Task success
  • Trust

Best forTeams about to launch, or about to double down on something unproven.

Typical timeline: 2–4 weeks

Prompt & response quality review

A read on what your system actually says: tone, accuracy, refusals and the answers that quietly damage trust, with the prompts rewritten.

What’s included

  • Sampled transcript review against your tone rules
  • System prompt rewrite and versioning
  • Refusal and safety wording review
  • Before-and-after comparison on a fixed set
  • Transcripts
  • Tone
  • Rewrite
  • OpenAI

Best forLive assistants whose answers no longer sound like the brand.

Typical timeline: 2–4 weeks

Accessibility review for AI interfaces

A WCAG 2.2 AA review of the parts that generic audits miss: streaming output, agent actions, voice input and content that changes under the reader.

What’s included

  • Screen-reader testing of streaming output
  • Keyboard control of every agent action
  • Voice input with a typed equivalent
  • Findings with fixes and retest
  • WCAG 2.2 AA
  • Screen readers
  • Keyboard
  • Playwright

Best forPublic-sector, regulated and enterprise products with conformance duties.

Typical timeline: Monthly, ongoing

Post-launch experience monitoring

A monthly read on how the experience is holding up: abandoned conversations, corrections, escalations and the answers people rejected.

What’s included

  • Instrumentation for AI-specific events
  • Monthly review of abandonment and corrections
  • Prompt set refreshed from real traffic
  • Prioritised design backlog
  • Monthly
  • Instrumented
  • Backlog

Best forProducts where the AI surface is now a main route to value.

Your brief

Tick “Add to brief” on any service, choose a package, then continue. Or enquire about one service directly.

Start a project

Ways to engage. Same team, same standard.

Three ways in, from a two-minute question to a formal RFQ. Each is read in full by the lead for the work, and anything already in your brief goes with it.

Or book a thirty-minute call

What are you sending?

  1. 01

    About 2 minutes4 required answers

    For a first conversation, a press request, or anything that does not need a scope yet.

    You get A reply from a lead, not a sales queue

  2. 02Most useful

    About 8 minutes5 short steps

    Goals, audiences, a budget band and timing. Enough for us to come back with a shape, not only questions.

    You get Options and a first scope after one call

  3. 03

    About 15 minutesYour documents attached

    Your pack, your deadlines, and the procurement and security rules the work must meet.

    You get Receipt confirmed and a named bid lead

How it is priced

Each package shows how it is priced. Every engagement starts with a written scope and a quote agreed before work begins.

  • Typical length
    1–3 weeks
    Pricing
    Fixed fee
  • Typical length
    4–12 weeks
    Pricing
    Fixed price
  • Typical length
    3–9 months
    Pricing
    Fixed price per milestone
  • Typical length
    Ongoing · 6-month minimum
    Pricing
    Monthly fee
Compare what each package includes
What every engagement package includes, and who it suits
PackageEvery engagement includesBest for
SprintOne fixed question, answered in one to three weeks.
  • Scope and outcome agreed before day one
  • One senior lead and the specialists the question needs
  • A working review every week
  • A decision-ready output, not a status deck
Discovery, a diagnostic, a prototype or a decision you need to make soon
ProjectA defined scope, delivered for a fixed price.
  • Statement of work with deliverables and acceptance criteria
  • A named project lead and a fixed team
  • A shared plan with dated checkpoints
  • Source files and IP transferred on delivery
Work you can describe up front: an identity, a system, a set of tools
MilestoneA larger build, split into gated phases you approve and pay for one at a time.
  • Phases with their own scope, output and sign-off
  • A go or no-go review at every gate
  • Re-planning between phases as you learn
  • Payment tied to accepted milestones
Programmes too big to fix in one contract, and teams that want control at each step
RetainerReserved monthly capacity to run, improve and extend what we built.
  • A reserved block of team time every month
  • Agreed response times for requests and fixes
  • A monthly review and a rolling backlog
  • Continuous improvement, not just upkeep
Brands and products after launch that need a steady team without hiring one

Questions

Asked plainly, answered plainly.

What buyers ask before AI Application Design work. Anything else, ask the team directly.

Ask the team
How is this different from the AI work in Technology & Intelligence?

That discipline engineers AI into business systems: agents, retrieval, infrastructure and production evaluation. AI Design shapes the experience people meet — the conversation, the controls and the way trust is earned on screen. On larger programmes the two run together, with design setting the acceptance criteria and engineering meeting them.

Do you design for one model or several?

The interface is designed to be model-agnostic. We prototype on the models that suit the task, including Gemini, OpenAI, Anthropic, Mistral and open-weight families, and design so that changing model is a configuration decision rather than a redesign.

How do you design for answers that are wrong?

By treating it as a normal state rather than an edge case. Sources and confidence are shown, a correction is one action away, consequential steps need approval, and there is always a route to a person. Failure states are designed in the same sprint as the happy path.

Can you work with our engineers rather than build it?

Yes. Most engagements end in a specification, components and a prompt set your team builds against. Where you need hands, engineers can join the build through Technology & Intelligence.

Can an AI interface be accessible?

It has to be. We design to WCAG 2.2 AA: streaming output announced to assistive technology, keyboard control of every agent action, no meaning carried by motion alone, and a typed equivalent for every voice interaction.

Also in AI Design

An assistant needs a reason and content to work with.

Each shares the models, evaluation sets and approval rules built here.

All of AI Design

04 / 04 · Adoption that survives the pilot

AI Strategy & Consulting

Bringing AI into the brand and marketing ecosystem through pilots and adoption roadmaps built to stick.
03 / 04 · The model layer of the brand

Brand AI Tools

Custom-tuned models, via Flux, Adobe Firefly, ComfyUI and more, that keep brand delivery consistent at scale.
02 / 04 · Volume without losing the eye

AI Content Studio

AI creatives, films and edits — model selection, automation and creative direction, with tools like Runway, Veo and ElevenLabs.

Let’s build what happens next.

Tell us what you’re building. We’ll answer straight.

Book a discovery call

Three ways to start

Every engagement starts with a written scope and a quote agreed before work begins.

Choose one of the three ways above